

Data quality management services
How thresholds get chosen, owned, and handled when breached.
Cross-industry engineering experience across regulated and high-growth sectors.
All Industries




“By 2028, 80% of GenAI business apps will be developed on existing data management platforms.” — Gartner

“Data-related issues cause 55% of organizations to avoid certain generative AI use cases.” — Deloitte
Choose it for an assessment and roadmap. It ends when leadership approves the target architecture.
Under managed delivery, we own scope through launch, then hand over code and runbooks.
Through team extension, our engineers join your squads, and your backlog directs them.
We operate pipelines after launch through on-call response, upgrades, and cost reviews.
You own it with consulting and dedicated teams. We own it in delivery and operations.
Team size and roles follow your source count, latency targets, and scope, agreed during discovery.
Outsourcing data engineering services long term can grow into a dedicated offshore development center.
Engagements often start as consulting, continue as delivery, and settle into managed operation.





 USA
 PL
 UA
 MX
 TR
Data engineering moves data from the systems that produce it to the systems that use it, in a shape those systems can rely on: ingestion, transformation, storage, orchestration, and the tests that say whether today’s run can be trusted. Platform migration and ongoing pipeline operation are the 2 other common scopes.
Data engineers own the pipelines, the storage, and the models underneath the metrics, while analysts own what the numbers mean and how they are presented. Teams that start with dashboards before pipelines are trustworthy get numbers people argue about instead of act on.
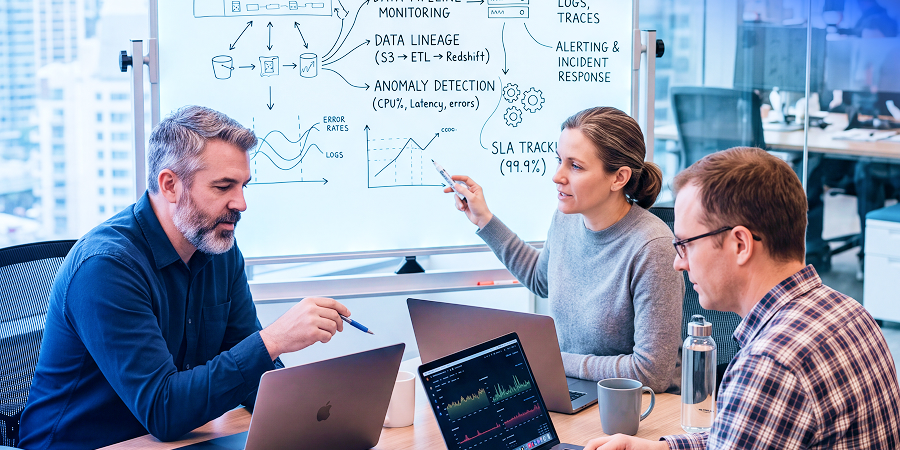
Tests gate the pipeline instead of reports describing it afterward: transformations are tested in CI, environments stay at parity, and monitoring watches the thresholds the data owners set. A run that fails is held instead of published, and threshold design and ownership belong to data quality management services.
Yes, all 3: delivered work includes AWS with Kafka, Kubernetes, Lambda, and CloudFormation, Azure on Databricks, Data Factory, and Synapse, and Google Cloud through BigQuery on an enterprise big data platform. The right choice is usually the cloud your team already operates, unless latency or cost profiles make it untenable.
In most cases we work with it, because a rebuild is justified only when the platform cannot meet the latency or cost profile you need. More often the problems are structural: no tests on transformations, no environment parity, and no owner for a dataset everyone depends on.
We review idle compute, node sizing, and repeated processing, then match capacity and loading patterns to the workload. Incremental loads, partition pruning, and job-scoped compute can reduce unnecessary processing as data volumes grow.
DataOps applies to pipelines what software teams take for granted: infrastructure defined as code, changes tested in CI before they reach production, parity between environments, and a defined rollback when a run is wrong. You need it once more than one person changes pipelines, which happens earlier than most teams expect.
The sequence matters more than the total: a first pipeline in production early, with tests and monitoring on it, sets the pattern every later source follows. Timelines scale with the number of source systems and the state of their documentation, not with data volume.
Compare the best data engineering consulting companies on evidence: which clouds and tools they have run in production, whether they operate what they build, and whether their case studies state throughput, cost, and latency. A data engineering consulting company that answers in those terms measures its work, and one that promises quality in general does not.
Both, and the choice depends on who owns the backlog: consulting produces an assessment and target architecture, project delivery builds a defined scope and hands it over, and a dedicated team works inside your backlog. Managed pipelines keep our engineers operating the platform after launch, and engagements often move from one model to another.